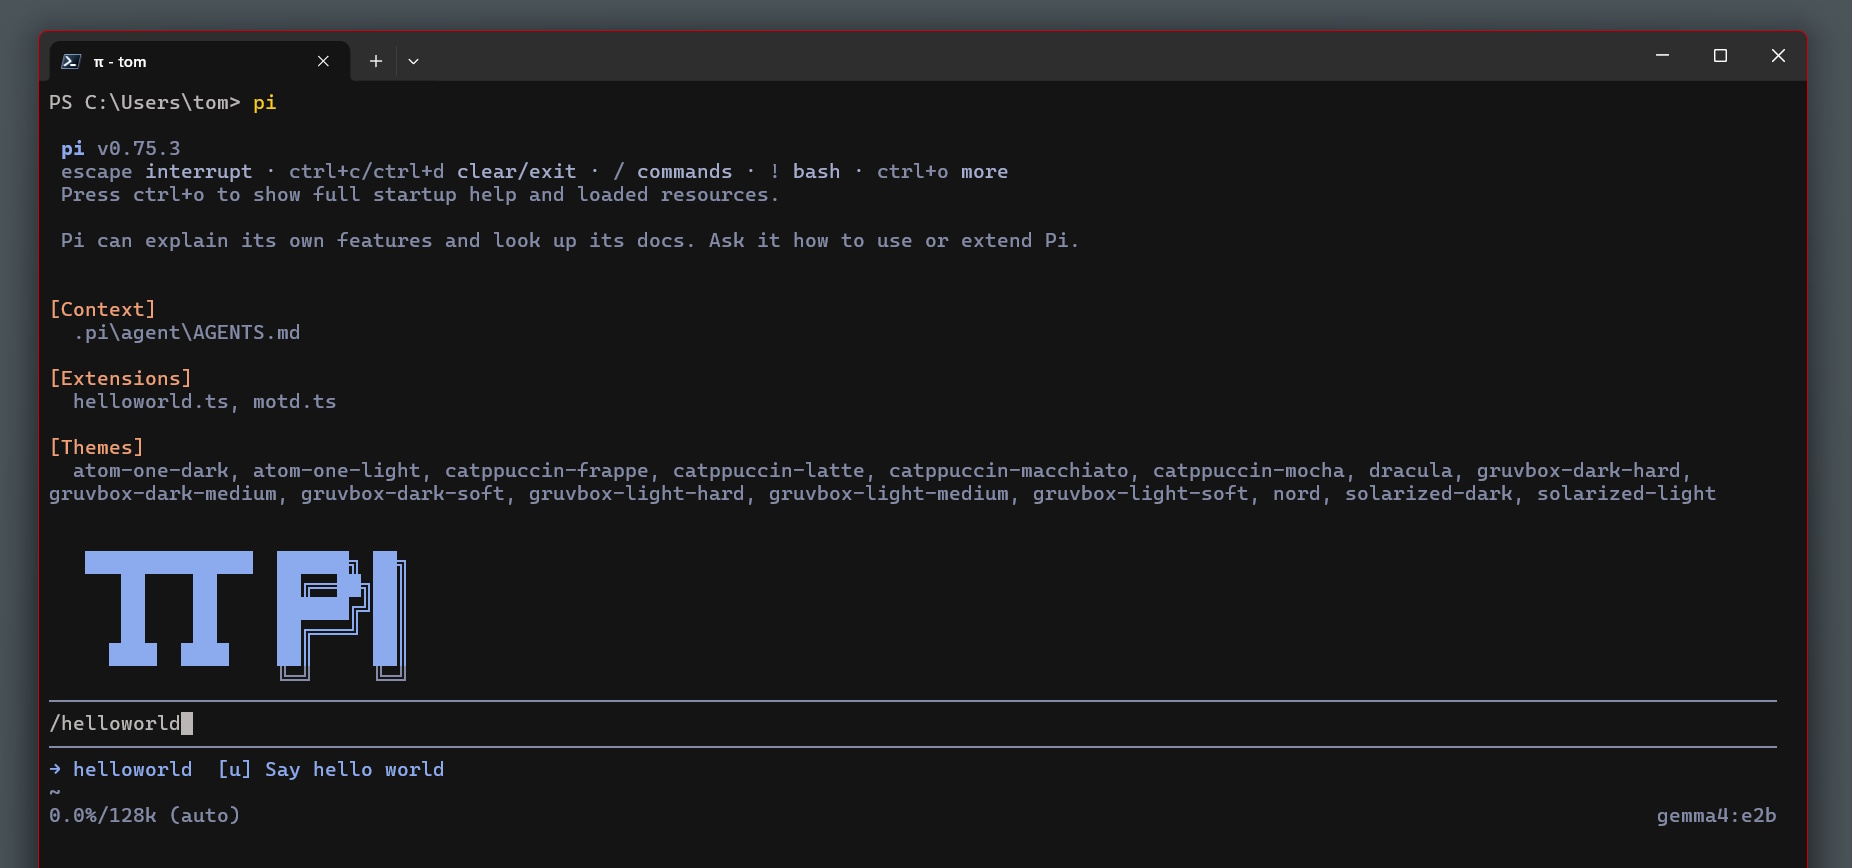
Terminal showing Pi Agent startup with skills and extensions loaded

Understanding Pi Agent's Extension Model: Context Files, Skills, and TypeScript Extensions

If like me, you’re spending an increasing amount of time learning Pi Agent - the minimal terminal coding harness - you’ll quickly hit the point where you want to bend it to your workflow. There are four different mechanisms for doing that: context files, prompt templates, skills, and TypeScript extensions. They look similar on the surface but they operate at completely different layers, and picking the wrong one means either burning context unnecessarily or writing TypeScript when a Markdown file would have done the job. ...
May 19, 2026 · 10 min · Tom Cocking

Give Claude Code Eyes Inside Your WSL2 Docker Containers

If you run Docker inside WSL2 on Windows 11, you’ve probably hit this wall: you open a Claude Code session in Windows Terminal, something goes wrong with a container, and Claude starts asking “can you paste the logs?”. Every. Single. Time. It breaks the flow completely. The whole point of an agentic coding tool is that it should be able to diagnose problems itself, not act as a fancy chat window that waits for you to do the investigation manually. ...

April 23, 2026 · 8 min · Tom Cocking

Running Ollama in a Proxmox LXC with NVIDIA GPU Passthrough

Running large language models locally is genuinely useful — no API costs, no rate limits, and your data stays on your own hardware. The catch is getting GPU acceleration working inside a Proxmox LXC container, which involves a few non-obvious steps around driver installation and cgroup device passthrough. Why LXC and not a VM? VM GPU passthrough wasn’t an option here — no iGPU meant the host would have had no display output once the card was handed off. LXC was the practical solution, and it turns out to be a good one anyway: containers share the host kernel directly, so the GPU stays bound to the host’s NVIDIA driver and the container accesses it via bind-mounted device nodes and cgroup permissions. On top of that, LXCs are lighter weight than VMs, with less overhead and near-instant startup times. For a dedicated service like Ollama, it’s a solid fit. ...

March 22, 2026 · 11 min · Tom Cocking

Testing Llama3.1 (8B) With LM Studio

MetaAI have done it again… Dropping llama3.1 under the (mostly) open source license and I have been putting it through its paces and benchmarking to find out how well it performs to models preiously tested: Testing Llama3 With LM Studio. Previously we took a look at llama3 in LM Studio which has made self hosted LLMs that rival paid services like ChatGPT and Claude possible; this time we are taking a look at llama through the lend of GPT4All. ...

July 28, 2024 · 10 min · Tom Cocking

Testing Llama3 With LM Studio

MetaAI have just introduced Llama 3 to the world and the open source community is already putting it through its paces and pushing to find the limits of what it can produce. One fantastic tool which has made self hosted LLMs that rival paid services like ChatGPT and Claude possible is LM Studio. With version 0.2.20 they bough about support for llama 3 along with a GGUF quantized 8 billion parameter version of the model. ...

April 19, 2024 · 13 min · Tom Cocking
How to generate artwork With Stable Diffusion Webui

Generating Artwork With Local Stable Diffusion on an RTX GPU: What Works and What Doesn't

As I write this, my computer’s Nvidia RTX GPU is busy converting watts into fictional images of robots and given the current cost of electricity, I am asking myself if the results it is producing are worth the resources required to produce them. In the article I hope to demonstrate how I am using AUTOMATIC1111/stable-diffusion-webui and Mikubill/sd-webui-controlnet to generate some borderline “art”. If you are looking to skip ahead to certain section, you can jump ahead using the table of contents above. ...

April 16, 2024 · 15 min · Tom Cocking